Wednesday, April 24, 2019

Human Test Scenario Bias in Autonomous Vehicle Validation

Human Test Scenario Bias:
Machine Learning perceives the world differently than you do. That means your intuition is not necessarily a good source for test planning.


Simulation-based testing (including especially closed-course testing of real vehicles) can suffer from a test planning bias. The problem is that a test plan is often made according to human perception of the scenario being tested. For example, a test scenario might be “child crossing in a painted cross-walk.” Details of the test scenario might explore various corner cases involving child clothing, size, weather conditions, scene clutter, and so on.

Commonly test scenarios map to a human-interpretable taxonomy of the system and environmental state space. However, autonomy systems might have a different internal state space representation than humans, meaning that they classify the world in ways that differ from how humans do so. This in turn can lead to a situation in which a human believes apparent complete coverage via a testing plan has been achieved, while in reality significant aspects of the autonomy system have not been tested.

As a hypothetical example, the autonomy system might have deduced that a human’s shirt color is a predictor of whether that human will step into a street because of accidental correlations in a training data set. But the test plan might not specify shirt color as a variable, because test designers did not realize it was a relevant autonomy feature for pedestrian motion prediction. That means that a human-designed vision test for an autonomous vehicle can be an excellent starting point to make sure that obstacles, pedestrians, and other objects can be detected by the system. But, more is required.

Machine-learning based systems are known to be vulnerable to learning bias that is not recognized by human testers, at least initially. Some such failures have been quite dramatic (e.g. Grush 2015). Thus, simplistic tests such as having an average body size white male in neutral summer clothing cross a street to test pedestrian avoidance do not demonstrate a robust safety capability. Rather, such tests tend to demonstrate a minimum performance capability.

Interpreting the results of human-constructed test designs, including humans interpreting why a particular on-road scenario failed, are also subject to human test scenario bias. A credible safety argument that relies upon human-constructed tests or human interpretation of root cause analysis in claiming that test failures have been fixed should address this pitfall.

(This is an excerpt of our SSS 2019 paper:  Koopman, P., Kane, A. & Black, J., "Credible Autonomy Safety Argumentation," Safety-Critical Systems Symposium, Bristol UK, Feb. 2019.  Read the full text here)

Wednesday, April 10, 2019

Safety Argument Consideration for Public Road Testing of Autonomous Vehicles

Beth Osyk and I are presenting our paper at SAE WCX today on how to argue sufficient road test safety for self-driving car technology.

See below slideshare or follow this link for presentation slides.

Preprint of paper here:
https://users.ece.cmu.edu/~koopman/pubs/koopman19_TestingSafetyCase_SAEWCX.pdf

Abstract:
Autonomous vehicle (AV) developers test extensively on public roads, potentially putting other road users at risk. A safety case for human supervision of road testing could improve safety transparency. A credible safety case should include: (1) the supervisor must be alert and able to respond to an autonomy failure in a timely manner, (2) the supervisor must adequately manage autonomy failures, and (3) the autonomy failure profile must be compatible with effective human supervision.\

Human supervisors and autonomous test vehicles form a combined human-autonomy system, with the total rate of observed failures including the product of the autonomy failure rate and the rate of unsuccessful failure mitigation by the supervisor. A difficulty is that human ability varies in a nonlinear way with autonomy failure rates, counter-intuitively making it more difficult for a supervisor to assure safety as autonomy maturity improves. Thus, road testing safety cases must account for both the expected failures during testing and the practical effectiveness of human supervisors given that failure profile. This paper outlines a high level safety case that identifies key factors for credibly arguing the safety of an onroad AV test program. A similar approach could be used to analyze potential safety issues for high capability semiautonomous production vehicles.


Wednesday, April 3, 2019

Nondeterministic Behavior and Legibility in Autonomous Vehicle Validation

Nondeterministic Behavior and Legibility:
How do you know your autonomous vehicle passed the test for the right reason? What if it just got lucky, or is gaming the test?


The nature of the algorithms used by autonomy systems creates problems for modelling and testing that go beyond typical safety critical software. Some autonomy algorithms, such as randomized path planning, are inherently non-deterministic. Others can be brittle, failing dramatically with subtle variations in data, such as perception false negatives induced by adversarial attacks (Szegedy at al. 2013) or false negatives induced by slight image degradation due to haze or defocus (Pezzementi et al. 2018).


A related issue is over-fitting to the test, in which an autonomy system over-fits and learns how to beat a fixed test. By analogy, this is the pitfall of the system cheating by having memorized the correct answers. A proposed way to deal with this risk is by randomly varying aspects of test cases. 

In such a fuzzing or variable testing approach it is important to randomly vary all relevant aspects of a problem. For example, varying geometries for traffic situations can be helpful, but probably does not address potential over-fitting for perception algorithms that perform object classification.

The use of potentially non-deterministic test scenarios combined with non-deterministic system behaviors and opaque system designs means it is difficult to know whether a system has passed a test, because there is no single correct answer. Rather, there must be some algorithmic way to determine whether a particular system response is acceptable or not, making that test oracle algorithm safety critical.

Moreover, it is possible that a system has passed a particular test by chance. For example, a pedestrian might be avoided due to a properly functioning detection and avoidance algorithm. But a pedestrian might also be avoided merely because a random path planner by chance picked a path that did not intersect the pedestrian, or responded to a completely unrelated aspect of the environment that caused it to pick a fortuitously safe path. Similarly, a pedestrian might be detected in one image, but undetected in another that differs in ways that are essentially imperceptible to a human.

It is unclear if resolving this issue requires solving the difficult problem of explainable AI (Gunning 2018). As a minimum, a credible safety argument will need to address the problem of how plans to test vehicles with less than a statistically valid amount of real-world exposure data can avoid these pitfalls. It seems likely that a credible argument will also have to establish that each type of test has been passed due to safe operation of the system rather than simply by chance (Koopman & Wagner 2018).

(This is an excerpt of our SSS 2019 paper:  Koopman, P., Kane, A. & Black, J., "Credible Autonomy Safety Argumentation," Safety-Critical Systems Symposium, Bristol UK, Feb. 2019.  Read the full text here)
  • Gunning, D. (2018), Explainable Artificial Intelligence (XAI), Defense Advanced Research Projects Agency, https://www.darpa.mil/program/explainable-artificial-intelligence (accessed October 27, 2018).
  • Koopman, P. & Wagner, M., (2018) "Toward a Framework for Highly Automated Vehicle Safety Validation," SAE World Congress, 2018. SAE-2018-01-1071.
  • Pezzementi, Z., Tabor, T., Yim, S., Chang, J., Drozd, B., Guttendorf, D., Wagner, M., Koopman, P., "Putting image manipulations in context: robustness testing for safe perception," IEEE International Symposium on Safety, Security, and Rescue Robotics (SSRR), Aug. 2018.
  • Szegedy, C., Zaremba, W., Sutskever, I., Bruna, J., Erhan, D., Goodfellow, I., Fer-gus, R. (2013) "Intriguing properties of neural networks." arXiv preprint arXiv:1312.6199 (2013).

Wednesday, March 27, 2019

Missing Rare Events in Autonomous Vehicle Simulation

Missing Rare Events in Simulation:
A highly accurate simulation and system model doesn't solve the problem of what scenarios to simulate. If you don't know what edge cases to simulate, your system won't be safe.


It is common, and generally desirable, to use vehicle-level simulation rather than on-road operation is used as a proxy field testing strategy. Simulation offers a number of potential advantages over field testing of a real vehicle including lower marginal cost per mile, better scalability, and reduced risk to the public from testing. Ultimately, simulation is based upon data that generates scenarios used to exercise the system under test, commonly called the simulation workload. The validity of the simulation workload is just as relevant as the validity of the simulation models and software.

Simulation-based validation is often accomplished with a weighting of scenarios that is intentionally different than the expected operational profile. Such an approach has the virtue of being able to exercise corner cases and known rare events with less total exposure than would be required by waiting for such situations to happen by chance in real-world testing (Ding 2017). To the extent that corner cases and known rare events are intentionally induced in physical vehicle field testing or closed course testing, those amount to simulation in that the occurrence of those events is being simulated for the benefit of the test vehicle.

A more sophisticated simulation approach should use a simulation “stack” with layered levels of abstraction. High level, faster simulation can explore system-level issues while more detailed but slower simulations, bench tests, and other higher fidelity validation approaches are used for subsystems and components (Koopman & Wagner 2018).

Regardless of the mix of simulation approaches, simulation fidelity and realism of the scenarios is generally recognized as a potential threat to validity. The simulation must be validated to ensure that it produces sufficiently accurate results for aspects that matter to the safety case. This might include requiring conformance of the simulation code and model data to a safety-critical software standard.


Even with a conceptually perfect simulation, the question remains as to what events to simulate. Even if simulation were to cover enough miles to statistically assure safety, the question would remain as to whether there are gaps in the types of situations simulated. This corresponds to the representativeness issue with field testing and proven in use arguments. However, representativeness is a more pressing matter if simulation scenarios are being designed as part of a test plan rather than being based solely on statistically significant amounts of collected field data.

Another way to look at this problem is that simulation can remove the need to do field testing for rare events, but does not remove determine what rare events matter. All things being equal, simulation does not reduce the number of road miles needed for data collection to observe rare events. Rather, it permits a substantial fraction of data collection to be done with a non-autonomous vehicle. Thus, even if simulating billions of miles is feasible, there needs to be a way to ensure that the test plan and simulation workload exercise all the aspects of a vehicle that would have been exercised in field testing of the same magnitude.

As with the fly-fix-fly anti-pattern, fixing defects identified in simulation requires additional simulation input data to validate the design. Simply re-running the same simulation and fixing bugs until the simulation passes invokes the “pesticide paradox.” (Beizer 1990) This paradox holds that a system which has been debugged to the point that it passes a set of tests can’t be considered completely bug free. Rather, it is simply free of the bugs that the test suite knows how to find, leaving the system exposed to bugs that might involve only very subtle differences from the test suite.

(This is an excerpt of our SSS 2019 paper:  Koopman, P., Kane, A. & Black, J., "Credible Autonomy Safety Argumentation," Safety-Critical Systems Symposium, Bristol UK, Feb. 2019.  Read the full text here)

Wednesday, March 20, 2019

Dealing with Edge Cases in Autonomous Vehicle Validation

Dealing with Edge Cases:
Some failures are neither random nor independent. Moreover, safety is typically more about dealing with unusual cases. This means that brute force testing is likely to miss important edge case safety issues.


A significant limitation to a field testing argument is the assumption of random independent failures inherent in the statistical analysis. Arguing that software failures are random and independent is clearly questionable, since multiple instances of a system will have identical software defects. 

Moreover, arguing that the arrival of exceptional external events is random and independent across a fleet is clearly incorrect in the general case. A few simple examples of correlated events between vehicles in a fleet include:
·        Timekeeping events (e.g. daylight savings time, leap second)
·        Extreme weather (e.g. tornado, tsunami, flooding, blizzard white-out, wildfires) affecting multiple systems in the same geographic area
·        Appearance of novel-looking pedestrians occurring on holidays (e.g. Halloween, Mardi Gras)
·        Security vulnerabilities being attacked in a coordinated way

For life-critical systems, proper operation in typical situations needs to be validated. But this should be a given. Progressing from baseline functionality (a vehicle that can operate acceptably in normal situations) to a safe system (a vehicle that safely handles unusual situations and unexpected situations) requires dealing with unusual cases that will inevitably occur in the deployed fleet.

We define an edge case as a rare situation that will occur only occasionally, but still needs specific design attention to be dealt with in a reasonable and safe way. The quantification of “rare” is relative, and generally refers to situations or conditions that will occur often enough in a full-scale deployed fleet to be a problem but have not been captured in the design or requirements process. (It is understood that the process of identifying and handling edge cases makes them – by definition – no longer edge cases. So in practice the term applies to situations that would not have otherwise been handled had special attempts not be made to identify them during the design and validation process.)

It is useful to distinguish edge cases from corner cases. Corner cases are combinations of normal operational parameters. Not all corner cases are edge cases, and the converse. An example of a corner case could be a driving situation with an iced over road, low sun angle, heavy traffic, and a pedestrian in the roadway. This is a corner case since each item in that list ought to be an expected operational parameter, and it is the combination that might be rare. This would be an edge case only if there is some novelty to the combination that produces an emergent effect with system behavior. If the system can handle the combination of factors in a corner case without any special design work, then it’s not really an edge case by our definition. In practice, even difficult-to-handle corner cases that occur frequently will be identified during system design.

Only corner cases that are both infrequent and present novelty due to the combination of conditions are edge cases. It is worth noting that changing geographic location, season of year, or other factors can result in different corner cases being identified during design and test, and leave different sets of edge cases unresolved. Thus, in practice, edge cases that remain after normal system design procedures could differ depending upon the operational design domain of the vehicle, the test plan, and even random chance occurrences of which corner cases happened to appear in training data and field trials.

Classically an edge case refers to a type of boundary condition that affects inputs or reveals gaps in requirements. More generally, edge cases can be wholly unexpected events, such as the appearance of a unique road sign, or an unexpected animal type on a highway. They can be a corner case that was thought to be impossible, such as an icy road in a tropical climate. They can also be an unremarkable (to a human), non-corner case that somehow triggers an autonomy fault or stumbles upon a gap in training data, such as a light haze that results in perception failure. The thing that makes something an edge case is that it unexpectedly activates a requirements, design, or implementation defect in the system.

There are two implications to the occurrence of such edge cases in safety argumentation. One is that fixing edge cases as they arrive might not improve safety appreciably if the population of edge cases is large due to the heavy tail distribution problem (Koopman 2018c). This is because removing even a large number of individual defects from an essentially infinite-size pool of rarely activated defects does not materially improve things. Another implication is that the arrival of edge cases might be correlated by date, time, weather, societal events, micro-location, or combinations of these triggers. Such a correlation can invalidate an assumption that losses from activation of a safety defect will result in small losses between the time the defect first activates and the time a fix can be produced. (Such correlated mishaps can be thought of as the safety equivalent of a “zero day attack” from the security world.)

It is helpful to identify edge cases to the degree possible within the constraints of the budget and resources available to a project. This can be partially accomplished via corner case testing (e.g. Ding 2017). The strategy here would be to test essentially all corner cases to flush out any that happen to present special problems that make them edge cases. However, some edge cases also require identifying likely novel situations beyond combinations of ordinary and expected scenario components. And other edge cases are exceptional to an autonomous system, but not obviously corner cases in the eyes of a human test designer.

Ultimately, it is unclear if it can ever be shown that all edge cases have been identified and corresponding mitigations designed into the system. (Formal methods could help here, but the question would be whether any assumptions that needed to be made to support proofs were themselves vulnerable to edge cases.) Therefore, for immature systems it is important to be able to argue that inevitable edge cases will be dealt with in a safe way frequently enough to achieve an appropriate level of safety. One potential argumentation approach is to aggressively monitor and report unusual operational scenarios and proactively respond to near misses and incidents before a similar edge case can trigger a loss event, arguing that the probability of a loss event from unhandled edge cases is sufficiently low. Such an argument would have to address potential issues from correlated activation of edge cases.

(This is an excerpt of our SSS 2019 paper:  Koopman, P., Kane, A. & Black, J., "Credible Autonomy Safety Argumentation," Safety-Critical Systems Symposium, Bristol UK, Feb. 2019.  Read the full text here)

  • Koopman, P. (2018c) "The Heavy Tail Safety Ceiling," Automated and Connected Vehicle Systems Testing Symposium, June 2018.
  • Ding, Z., “Accelerated evaluation of automated vehicles,” http://www-personal.umich.edu/~zhaoding/accelerated-evaluation.html on 10/15/2017.


Monday, March 11, 2019

The Fly-Fix-Fly Antipattern for Autonomous Vehicle Validation

Fly-Fix-Fly Antipattern:
Brute force mileage accumulation to fix all the problems you see on the road won't get you all the way to being safe. For so very many reasons...


This A400m crash was caused by corrupted software calibration parameters.
In practice, autonomous vehicle field testing has typically not been a deployment of a finished product to demonstrate a suitable integrity level. Rather, it is an iterative development approach that can amount to debugging followed by attempting to achieve improved system dependability over time based on field experience. In the aerospace domain this is called a “fly-fix-fly” strategy. The system is operated and each problem that crops up in operations is fixed in an attempt to remove all defects. While this can help improve safety, it is most effective for a rigorously engineered system that is nearly perfect to begin with, and for which the fixes do not substantially alter the vehicle’s design in ways that could produce new safety defects.


It's a moving target: A significant problem with argumentation based on fly-fix-fly occurs when designers try to take credit for previous field testing despite a major change. When arguing field testing safety, it is generally inappropriate to take credit for field experience accumulated before the last change to the system that can affect safety-relevant behaviour. (The “small change” pitfall has already been discussed in another blog post.)

Discounting Field Failures: There is no denying the intuitive appeal to an argument that the system is being tested until all bugs have been fixed. However, this is a fundamentally flawed argument. That is because this amounts to saying that no matter how many failures are seen during field testing, none of them “count” if a story can be concocted as to how they were non-reproducible, fixed via bug patches, and so on.

To the degree such an argument could be credible, it would have to find and fix the root cause of essentially all field failures. It would further have to demonstrate (somehow) that the field failure root cause had been correctly diagnosed, which is no small thing, especially if the fix involves retraining a machine-learning based system. 

Heavy Tail: Additionally, it would have to argue that a sufficiently high fraction of field failures have actually been encountered, resulting in a sufficiently low probability of encountering novel additional failures during deployment.  (Probably this would be an incorrect argument if, as expected, field failure types have a heavy tail distribution.)

Fault Reinjection: A fly-fix-fly argument must also address both the fault reinjection problem. Fault reinjection occurs when a bug fix introduces a new bug as a side effect of that fix. Ensuring that this has not happened via field testing alone requires resetting the field testing clock to zero after every bug fix. (Hybrid arguments that include rigorous engineering analysis are possible, but simply assuming no fault reinjection without any supporting evidence is not credible.)

It Takes Too Long: It is difficult to believe an argument that claims that a fly-fix-fly process alone (without any rigorous engineering analysis to back it up) will identify and fix all safety-relevant bugs. If there is a large population of bugs that activate infrequently compared to the amount of field testing exposure, such a claim would clearly be incorrect. Generally speaking, fly-fix-fly requires an infeasible amount of operation to achieve the ultra-dependable results required for life critical systems, and typically makes unrealistic assumptions such as no new faults are injected by fixing a fault identified in testing (Littlewood and Strigini 1996). A specific issue is the matter of edge cases, discussed in an upcoming blog post.

(This is an excerpt of our SSS 2019 paper:  Koopman, P., Kane, A. & Black, J., "Credible Autonomy Safety Argumentation," Safety-Critical Systems Symposium, Bristol UK, Feb. 2019.  Read the full text here)
  • Littlewood, B., Strigini, L. (1993) “Validation of Ultra-High Dependability for Soft-ware-Based Systems,” Communications of the ACM, 36(11):69-80, November 1993.


Thursday, March 7, 2019

The Insufficient Testing Pitfall for autonomous system safety

The Insufficient Testing Pitfall:
Testing less than the target failure rate doesn't prove you are safe.  In fact you probably need to test for about 10x the target failure rate to be reasonably sure you've met it. For life critical systems this means too much testing to be feasible.


In a field testing argumentation approach a fleet of systems is tested in real-world conditions to build up confidence. At a certain point the testers declare that the system has been demonstrated to be safe and proceed with production deployment.

An appropriate argumentation approach for field testing is that a sufficiently large number of exposure hours have been attained in a highly representative real-world environment. In other words, this is a variant of a proven in use argument in which the “use” was via testing rather than a production deployment. As such, the same proven in use argumentation issues apply, including especially the needs for representativeness and statistical significance. However, there are additional pitfalls encountered in field testing that must also be dealt with.

Accumulating an appropriate amount of field testing data for high dependability systems is challenging. In general, real-world testing needs to last approximately 3 to 10 times the acceptable mean time between hazardous failure to provide statistical significance (Kalra and Paddock 2016). For life-critical testing this can be an infeasible amount of testing (Butler and Finelli 1993, Littlewood and Strigini 1993).

Even if a sufficient amount of testing has been performed, it must also be argued that the testing is representative of the intended operational environment. To be representative, the field testing must at least have an operational profile (Musa et al. 1996) that matches the types of operational scenarios, actions, and other attributes of what the system will experience when deployed. For autonomous vehicles this includes a host of factors such as geography, roadway infrastructure, weather, expected obstacle types, and so on.

While the need to perform a statistically significant amount of field testing should be obvious, it is common to see plans to build public confidence in a system via comparatively small amounts of public field testing. (Whether there is additional non-public-facing argumentation in place is unclear in many of these cases.)

To illustrate the magnitude of the problem, in 2016 there were 1.18 fatalities per 100 million vehicle miles traveled in the United States, making the Mean Time Between Failures (MTBF) with respect to fatalities by a human driver 85 million miles (NHTSA 2017). Assuming an exponential failure distribution, for a given MTBF the required test time in which r failures occur can be computed with confidence α using a chi square distribution (Morris 2018):

Required Test Time =  χ2(α, 2r + 2)(MTBF)/2

(If you want to try out some example numbers, try out this interactive calculator at https://reliabilityanalyticstoolkit.appspot.com/mtbf_test_calculator)

Based on this, a single-occupant system needs to accumulate 255 million test miles with no fatalities to be 95% sure that the mean time is only 85 million miles. If there is a mishap during that time, more testing is required to distinguish normal statistical fluctuations from a lower MTBF: a total of 403 million miles to reach 95% confidence. If a second mishap occurs, 535 million miles of testing are needed, and so on. Additional testing might also be needed if the system is changed, as discussed in a subsequent section. Significantly more testing would also be required to ensure a comparable per-occupant fatality rate for multi-occupant vehicle configurations.

Attempting to use a proxy metric such as rate of non-fatal crashes and extrapolate to fatal mishaps requires also substantiating the assumption that the mishap profiles will be the same for autonomous systems as they are for human drivers. (See the human filter pitfall previously discussed.)

(This is an excerpt of our SSS 2019 paper:  Koopman, P., Kane, A. & Black, J., "Credible Autonomy Safety Argumentation," Safety-Critical Systems Symposium, Bristol UK, Feb. 2019.  Read the full text here)


  • Kalra, N., Paddock, S., (2016) Driving to Safety: how many miles of driving would it take to demonstrate autonomous vehicle reliability? Rand Corporation, RR-1479-RC, 2016.
  • Butler, Finelli (1993) “The infeasibility of experimental quantification of life-critical software reliability,” IEEE Trans. SW Engr. 19(1):3-12, Jan 1993.
  • Littlewood, B., Strigini, L. (1993) “Validation of Ultra-High Dependability for Software-Based Systems,” Communications of the ACM, 36(11):69-80, November 1993.
  • Musa, J., Fuoco, G., Irving, N., Kropfl, D., Juhlin, B., (1996) “The Operational Profile,” Handbook of Software Reliability Engineering, pp. 167-216, 1996.
  • NHTSA (2017) Traffic Safety Facts Research Note: 2016 Fatal Motor Vehicle Crashes: Overview. U.S. Department of Transportation National Highway Traffic Safety Administration. DOT HS-812-456.
  • Morris, S. (2018) Reliability Analytics Toolkit: MTBF Test Time Calculator. https://reliabilityanalyticstoolkit.appspot.com/mtbf_test_calculator. Reliability Analytics. (accessed December 12, 2018)


Tuesday, March 5, 2019

The Human Filter Pitfall for autonomous system safety

The Human Filter Pitfall:
Using data from human-driven vehicles has gaps corresponding to situations a human knows to avoid getting into in the first place, but which an autonomous system might experience.


The operational history (and thus the failure history) of many systems is filtered by human control actions, preemptive incident avoidance actions and exposure to operator-specific errors. This history might not cover the entirety of the required functionality, might primarily cover the system in a comparatively low risk environment, and might under-represent failures that manifest infrequently with human operators present.

From a proven in use perspective, trying to use data from human-operated vehicles, such as historical crash data, might be insufficient to establish safety requirements or a basis for autonomous vehicle safety metrics. The situations in which human-operated vehicles have trouble may not be the same situations that autonomous systems find difficult. It is easy to overlook the situations humans are good at navigating but which may cause problems for autonomous systems when looking at existing data of situations that humans get wrong. An autonomous system cannot be validated only against problematic human driving scenarios (e.g. NHTSA (2007) pre-crash typology). The autonomy might handle these hazardous situations perfectly yet fail often in otherwise common situations that humans regularly perform safely. Thus, an argument that a system is safe solely because it has been checked to properly handle situations that have high rates of human mishaps is incomplete in that it does not address the possibility of new types of mishaps.

This pitfall can also occur when arguing safety for existing components being used in a new system. For example, consider a safety shutdown system used as a backup to a human operator, such as an Automated Emergency Braking (AEB) system. It might be that human operators tend to systematically avoid putting an AEB system in some particular situation that it has trouble handling. As a hypothetical example, consider an AEB system that has trouble operating effectively when encountering obstacles in tight curves. If human drivers habitually slow down on such curves there might be no significant historical data indicating this is a potential problem, and autonomous vehicles that operate at the vehicle dynamics limit rather than a sight distance limit on such curves will be exposed to collisions due to this bias in historical operational data that hides an AEB weakness. A proven-in-use argument in such a situation has a systematic bias and is based on incomplete evidence. It could be unsafe, for example, to base a safety argument primarily upon that AEB system for a fully autonomous vehicle, since it would be exposed to situations that would normally be pre-emptively handled by a human driver, even though field data does not directly reveal this as a problem.

(This is an excerpt of our SSS 2019 paper:  Koopman, P., Kane, A. & Black, J., "Credible Autonomy Safety Argumentation," Safety-Critical Systems Symposium, Bristol UK, Feb. 2019.  Read the full text here)

  • NHTSA (2007) Pre-Crash Scenario Typology for Crash Avoidance Research, Na-tional Highway Traffic Safety Administration, DOT HS-810-767, April 2007

Thursday, February 28, 2019

The Discounted Failure Pitfall for autonomous system safety

The Discounted Failure Pitfall:
Arguing that something is safe because it has never failed before doesn't work if you keep ignoring its failures based on that reasoning.


A particularly tricky pitfall occurs when a proven in use argument is based upon a lack of observed field failures when field failures have been systematically under-reported or even not reported at all. In this case, the argument is based upon faulty evidence.

One way that this pitfall manifests in practice is that faults that result in low consequence failures tend to go unreported, with system redundancy tending to reduce the consequences of a typical incident. It can take time and effort to report failures, and there is little incentive to report each incident if the consequence is small, the system can readily continue service, and the subjective impression is that the system is perceived as overall safe. Perversely, reporting numerous recovered malfunctions or warnings can actually increase user confidence in a system even while events go unreported. This can be a significant issue when removing backup systems such as mechanical interlocks based on a lack of reported loss events. If the interlocks were keeping the system safe but interlock or other failsafe engagements go unreported, removing those interlocks can be deadly. Various aspects of this pitfall came into play in the Therac 25 loss events (Leveson 1993).

An alternate way that this pitfall manifests is when there is a significant economic or other incentive for suppressing or mischaracterizing the cause of field failures. For example, there can be significant pressure and even systematic approaches to failure reporting and analysis that emphasize human error over equipment failure in mishap reporting (Koopman 2018b). Similarly, if technological maturity is being measured by a trend of reduced safety mechanism engagements (e.g. autonomy disengagements during road testing (Banerjee et al. 2018)), there can be significant pressure to artificially reduce the number of events reported. Claiming proven in use integrity for a component subject to artificially reduced or suppressed error reports is again basing an argument on faulty evidence.

Finally, arguing that a component cannot be unsafe because it has never caused a mishap before can result in systems that are unsafe by induction. More specifically, if each time you argue it wasn't that component's fault, and therefore don't attribute cause to that component, then you can continue that behavior forever, all the while denying that an unsafe component is OK.

(This is an excerpt of our SSS 2019 paper:  Koopman, P., Kane, A. & Black, J., "Credible Autonomy Safety Argumentation," Safety-Critical Systems Symposium, Bristol UK, Feb. 2019.  Read the full text here)

  • Leveson, N. (1993) An investigation of the Therac-25 Accidents, IEEE Computer, July 1993, pp. 18-41.
  • Koopman, P. (2018b), "Practical Experience Report: Automotive Safety Practices vs. Accepted Principles," SAFECOMP, Sept. 2018.
  • Bannerjee, S., Jha, S., Cyriac, J., Kalbarczyk, Z, Iyer, R., (2018) “Hands Off the Wheel in Autonomous Vehicles?: A Systems Perspective on over a Million Miles of Field Data,” 48th Annual IEEE/IFIP International Conference on Dependable Systems and Networks (DSN), 2018.

Tuesday, February 26, 2019

The “Small” Change Fallacy for autonomous system safety

The “small” change fallacy:
In software, even a single character source code can cause catastrophic failure.  With the possible exception of a very rigorous change analysis process, there is no such thing as a "small" change to software.


Headline: July 22, 1969: Mariner 1 Done In By A Typo

Another threat to validity for a proven in use strategy is permitting “small” changes without re-validation (e.g. as implicitly permitted by (NHTSA 2016), which requires an updated safety assessment for significant changes). Change analysis can be difficult in general for software, and ineffective for software that has high coupling between modules and resultant complex inter-dependencies.

Because even one line of bad code can result in a catastrophic system failure, it is highly questionable to argue that a change is “small” because it only affects a small fraction of the source code base. Rigorous analysis should be performed on the change and its possible effects, which generally requires analysis of design artifacts beyond just source code.

A variant of this pitfall is arguing that a particular type of technology is generally “well understood” and implying based upon this that no special attention is required to ensure safety. There is no reason to expect that a completely new implementation – potentially by a different development team with a different engineering process – has sufficient safety integrity simply because it is not a novel function to the application domain.

(This is an excerpt of our SSS 2019 paper:  Koopman, P., Kane, A. & Black, J., "Credible Autonomy Safety Argumentation," Safety-Critical Systems Symposium, Bristol UK, Feb. 2019.  Read the full text here)
  • NHTSA (2016) Federal Automated Vehicles Policy, National Highway Transporta-tion System Administration, U.S. Department of Transportation, September 2016. 

Thursday, February 21, 2019

Assurance Pitfalls When Using COTS Components

Assurance Pitfalls When Using COTS Components:
Using a name-brand, familiar component doesn't automatically ensure safety.


It is common to repurpose Commercial Off-The-Shelf (COTS) software or components for use in critical autonomous vehicle applications. These include components originally developed for other domains such as mine safety, low volume research components such as LIDAR units, and automotive components such as radars previously used in non-critical or less critical ADAS applications.

Generally such COTS components are being used in a somewhat different way than the original non-critical commercial purpose, and are often modified for use as well. Moreover, even field proven automotive components are typically customized for each vehicle manufacturer to conform to customer-specific design requirements. When arguing that a COTS item is proven in use, it is important to account for at least whether there is in fact sufficient field experience, whether the field experience is for a previous or modified version of the component, and other factors such as potential supply-chain changes, manufacturing quality fade, and the possibility of counterfeit goods.

In some cases we have seen proven in use arguments attempted for which the primary evidence relied upon is the reputation of a manufacturer based on historical performance on other components. While purchasing from a reputable manufacturer is often a good start, a brand name label by itself does not necessarily demonstrate that a particular component is fit for purpose, especially if a complex supply chain is involved.

COTS components can be problematic if they don't come with the information needed for safety assessment. (Hint: source code is only a starting point. But often even that isn't provided.) While third party certification certainly is not a panacea, looking for independent evaluation that relevant technical, development process, and assurance process activities have been performed is a good start to making sure COTS components are fit for purpose.

(This is an excerpt of our SSS 2019 paper:  Koopman, P., Kane, A. & Black, J., "Credible Autonomy Safety Argumentation," Safety-Critical Systems Symposium, Bristol UK, Feb. 2019.  Read the full text here)

Tuesday, February 19, 2019

Proven In Use: The Violated Assumptions Pitfall for Autonomous Vehicle Validation

The Violated Assumptions Pitfall:
Arguing something is Proven In Use must address whether the new use has sufficiently similar assumptions and operational conditions as the old one.


The proven in use argumentation pattern uses field experience of a component (or, potentially, an engineering process) to argue that field failure rates have been sufficiently low to assure a necessary level of integrity.

Historically this has been used as a way to grandfather existing components into new safety standards (for example, in the process industry under IEC 61508). The basis of the argument is generally that if a huge number of operational hours of experience in the actual application have been accumulated with a sufficiently low number of safety-relevant failures, then there is compelling experimental data supporting the integrity claim for a component. We assume in this section that sufficient field experience has actually been obtained to make a credible argument. A subsequent section on field testing addresses the issue of how much experience is required to make a statistically valid claim.

A plausible variant could be that a component is initially deployed with temporary additional level of redundancy or other safety backup mechanism such as using a Doer/Checker pair. (By analogy, the Checker is a set of training wheels for a child learning to ride a bicycle.) When sufficient field experience has been accumulated to attain confidence regarding the safety of the main system, the additional safety mechanism might be removed to reduce cost.

For autonomous vehicles, the safety backup mechanism frequently manifests as a human safety driver, and the argument being made is that a sufficient amount of safe operation with a human safety driver enables removal of that safety driver for future deployments. The ability of a human safety driver to adequately supervise autonomy is itself a difficult topic (Koopman and Latronico 2019, Gao 2016), but is beyond the scope of this paper.

A significant threat to validity for proven in use argumentation is that the system will be used in an operational environment that differs in a safety-relevant way from its field history. In other words, a proven in use argument is invalidated if the component in question is exposed to operational conditions substantively different than the historical experience.

Diverging from historical usage can happen in subtle ways, especially for software components. Issues of data value limits, timing, and resource exhaustion can be relevant and might be caused by functionally unrelated components within a system. Differences in fault modes, sensor input values, or the occurrence of exceptional situations can also cause problems.

A proven in use safety argument must address how the risk of the system being deployed outside this operational profile is mitigated (e.g. by detecting distributional shifts in the environment, by external limitations on the environment, or by procedural mitigations). It is important to realize that an operational profile for a safety critical system must include not only typical cases, but also rare but expected edge cases as well. An even more challenging issue is that there might be operational environment assumptions that designers do not realize are being made, resulting in a residual risk of violated assumptions even after a thorough engineering review of the component reuse plan.

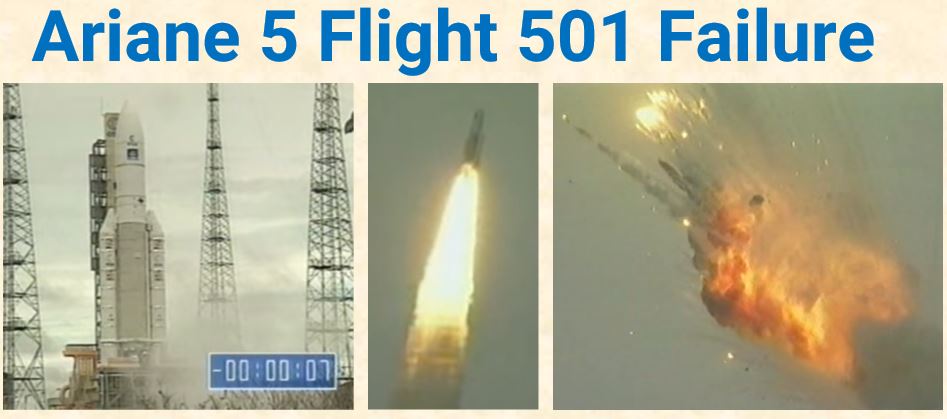
A classic example of this pitfall is the failure of Ariane 5 flight 501. That mishap involved reusing an inertial navigation system from the Ariane 4 design employing a proven in use argument (Lyons 1996). A contributing factor was that software functionality used by Ariane 4 but not required for Ariane 5 flight was left in place to avoid having to requalify the component.

(This is an excerpt of our SSS 2019 paper:  Koopman, P., Kane, A. & Black, J., "Credible Autonomy Safety Argumentation," Safety-Critical Systems Symposium, Bristol UK, Feb. 2019.  Read the full text here)
  • Koopman, P. and Latronico, B., (2019) Safety Argument Considerations for Public Road Testing of Autonomous Vehicles, SAE WCX, 2019.
  • Gao, F. (2016) Modeling Human Attention and Performance in Automated Environ-ments with Low Task Loading, Ph.D. Dissertation, Massachusetts Institute of Technolo-gy, Feb. 2016.

Thursday, February 14, 2019

Pitfall: Arguing via Compliance with an Inappropriate Safety Standard

For a standard to help ensure you are actually safe, not only do you have to actually follow it, but it must be a suitable standard in domain, scope, and level of integrity assured.  Proprietary safety standards often don't actually make you safe.


Historically some car makers have used internal, proprietary software safety guidelines as their way of attempting to assure an appropriate level of safety (Koopman 2018b). If a safety argument is based in part upon conformance to a safety standard, it is essential that the comprehensiveness of the safety standard itself be supported by evidence. For public standards that argument can involve group consensus by experts, public scrutiny, assessments of historical effectiveness, improvement in response to loss events, and general industry acceptance.

On the other hand, proprietary standards lack at least public scrutiny, and often lack other aspects such as general industry acceptance as well as falling short of accepted practices in technically substantive ways. One potential approach to argue that a proprietary safety standard is adequate is to map it to a publicly available standard, although there might be other viable argumentation approaches.

Sometimes arguing compliance with a well-known and documented industry safety standard may be inadequate for a particular safety case. Although all passenger vehicle subsystems in the United States must comply with the Federal Motor Vehicle Safety Standards (FMVSS) issued by the National Highway Transportation Safety Administration (NHTSA), compliance with these standards alone concentrates on mechanical and electrical issues, and only high level electronics functionality. FMVSS compliance is insufficient for a safety case that must encompass software (Koopman 2018b).

Similarly, use of particular standards might be an accepted or recommended practice, but not a means of ensuring safety. For example, the use of AUTOSAR (Autosar.org 2018) and Model Based Design techniques are sometimes proposed as indicators of safe software, but use of these technologies has essentially no predictive power with respect to system safety.

 For automotive systems with safety-critical software, ISO 26262 is typically an appropriate standard, although other standards such as IEC 61508 (IEC 1998) can be relevant as well. For some autonomous system functions, conformance to ISO PAS 21448 (ISO 2018) might well be appropriate. A new standard, UL 4600, is specifically intended to cover autonomous vehicles and is expected to be introduced in 2019.

Arguments of the form "technology X, standard Y, or methodology Z is adequate because it has historically produced safe systems in that past" should address the potential issues with "proven in use" argumentation considered in the following section.

(This is an excerpt of our SSS 2019 paper:  Koopman, P., Kane, A. & Black, J., "Credible Autonomy Safety Argumentation," Safety-Critical Systems Symposium, Bristol UK, Feb. 2019.  Read the full text here)

  • Autosar.org (2018) The Standard Software Framework for Intelligent Mobility, https://www.autosar.org/ accessed Nov. 5, 2018.
  • Koopman, P. (2018b), "Practical Experience Report: Automotive Safety Practices vs. Accepted Principles," SAFECOMP, Sept. 2018.
  • IEC (1998) IEC 61508: Functional Safety of Electrical/Electronic/Programmable Electronic Safety-related Systems, International Electronic Commission, December, 1998.
  • ISO (2018) Road vehicles – Safety of the Intended Function, ISO/PRF PAS 21448 (under development), International Standards Organization, 2018.